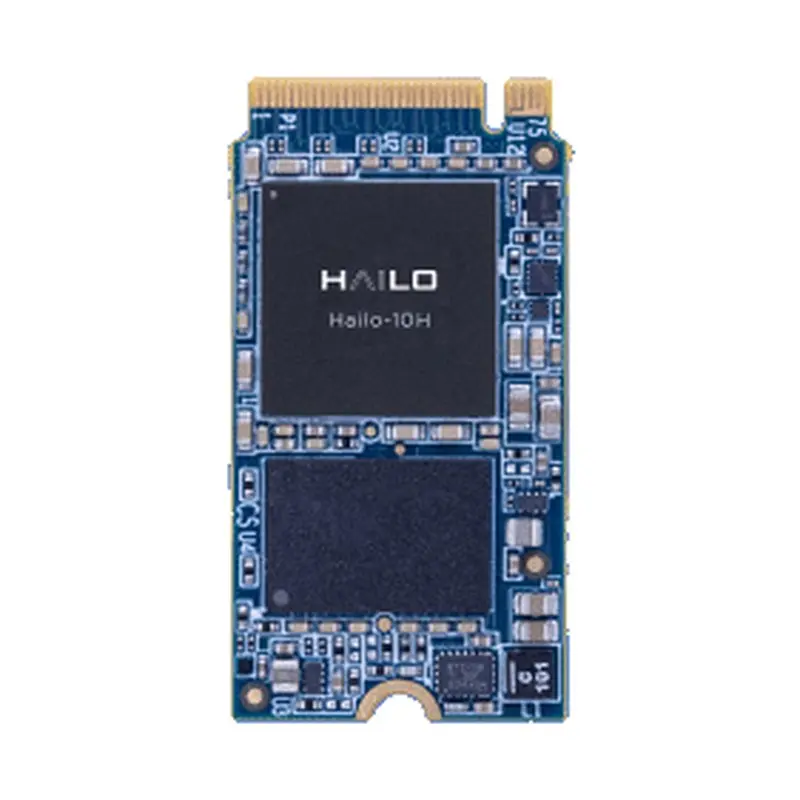
The Hailo-10H M.2 AI Acceleration Module, part number HM22HB2C2HAE, combines a Hailo-10H accelerator with 4GB of on-module LPDDR4/4X memory in an M.2 2242 Key M format. It is designed to add dedicated AI inference processing to a compatible PC, embedded computer, or industrial edge system.
The module supports suitable generative AI and computer vision applications. Development teams can evaluate supported language and vision-language models alongside workloads such as image understanding, object detection, and video analytics. Running inference on the local system can help an application respond close to its data source. Model availability and performance depend on the selected model, its optimization, and the complete host configuration.
The Hailo-10H provides up to 40 TOPS at INT4 precision or 20 TOPS at INT8 precision. These are separate performance ratings for different numerical precision modes. When selecting a model, engineers should consider its precision requirements, memory use, input size, and expected response time. The module’s 4GB memory capacity is a key consideration for generative AI workloads, particularly when comparing models of different sizes.
HM22HB2C2HAE uses PCIe Gen 3 x4 through an M.2 Key M connection. The host must provide a suitable socket, the required PCIe connectivity, and a mounting position for a 22 × 42 mm module. An M.2 slot’s physical appearance alone does not establish software or electrical compatibility, so the host design and Hailo integration requirements should be checked together.
Hailo specifies this extended temperature module for −40°C to 85°C operation and lists 2.5 W typical power consumption. Actual power and heat output depend on the workload. Board placement, airflow, and the system’s cooling design should therefore be assessed during integration.
For software development, Hailo provides the Dataflow Compiler for preparing supported neural network models and HailoRT for running inference. Hailo lists TensorFlow, TensorFlow Lite, Keras, PyTorch, and ONNX among its supported development frameworks, with x86 and Arm hosts and Linux, Windows, and Android operating systems.