Precision You Can Trust
NABL-Accredited Calibration | Available on Request
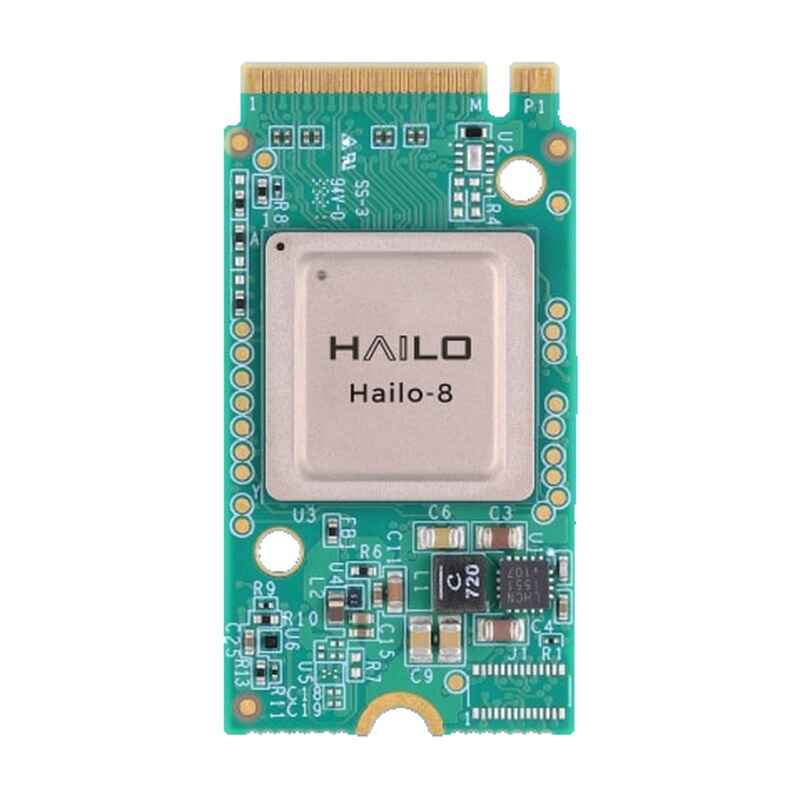
The Hailo-8 M.2 AI Acceleration HM218B1C2XAE Module delivers up to 26 TOPS of AI inference performance for real-time edge applications. Available in M.2 Key M, Key B+M and Key A+E form factors, it supports PCIe Gen 3 connectivity, x86 and ARM host platforms, and extended operating temperatures from -40°C to +85°C..
The Hailo-8 M.2 AI Acceleration Module (HM218B1C2XAE) is a high-performance edge AI accelerator module designed to add dedicated deep-learning inference capability to embedded systems, industrial PCs, edge gateways and other computing platforms equipped with an M.2 interface.
Powered by the Hailo-8 AI processor, the module delivers up to 26 TOPS of AI compute performance. It enables deep neural network inference directly at the edge, helping reduce latency, cloud dependency and network bandwidth requirements.
The Hailo-8 uses a structure-driven dataflow architecture developed specifically for neural-network workloads. This enables efficient distribution of AI processing tasks while maintaining the power efficiency needed for embedded and industrial systems.
The module is well suited for computer vision and intelligent video analytics, including object detection, classification, tracking, automated visual inspection and multi-camera AI processing. It supports multi-stream and multi-model inference, allowing compatible edge systems to execute several AI workloads simultaneously.
The HM218B1C2XAE module connects to the host system through PCIe Gen 3, providing high-speed communication for real-time AI workloads. It can be integrated into compatible x86 and ARM-based computing platforms.
Hailo provides a complete software ecosystem for model development and deployment, including the Hailo Dataflow Compiler, HailoRT runtime and Hailo Model Zoo. The platform supports widely used AI frameworks including TensorFlow, TensorFlow Lite, Keras, PyTorch and ONNX.
The Hailo-8 M.2 AI Acceleration Module is suitable for edge applications where high AI performance, low latency, compact integration and efficient local inference are required.
Up to 26 TOPS AI inference performance
Powered by the Hailo-8 AI Processor
High power efficiency for edge AI applications
Real-time, low-latency deep-learning inference
Supports simultaneous multi-stream and multi-model processing
Available in M.2 Key M, Key B+M and Key A+E
PCIe Gen 3.0 interface
Up to 4 PCIe lanes with Key M
Compatible with x86 and ARM host processors
Supports Linux and Windows
Compatible with TensorFlow, TensorFlow Lite, Keras, PyTorch and ONNX
Extended temperature operation from -40°C to +85°C
Suitable for compact embedded and industrial systems
Standard M.2 form factors simplify integration
Supports Hailo Dataflow Compiler, HailoRT and Model Zoo
Designed for scalable multi-camera and multi-model AI processing
| Specification | Hailo-8 M.2 Module |
|---|---|
| AI Performance | Up to 26 TOPS |
| AI Processor | Hailo-8 |
| Form Factor Options | M.2 Key M, Key B+M, Key A+E |
| Key M / B+M Dimensions | 22 × 42 mm with extensions to 22 × 60 mm and 22 × 80 mm |
| Key A+E Dimensions | 22 × 30 mm |
| Interface | PCIe Gen 3.0 |
| PCIe Lanes | 2 lanes, 4 lanes with Key M |
| Supported Host Architectures | x86, ARM |
| Supported OS | Linux, Windows |
| AI Frameworks | TensorFlow, TensorFlow Lite, Keras, PyTorch, ONNX |
| Extended Temperature Range | -40°C to +85°C |
| Multi-Stream Processing | Supported |
| Multi-Model Processing | Supported |