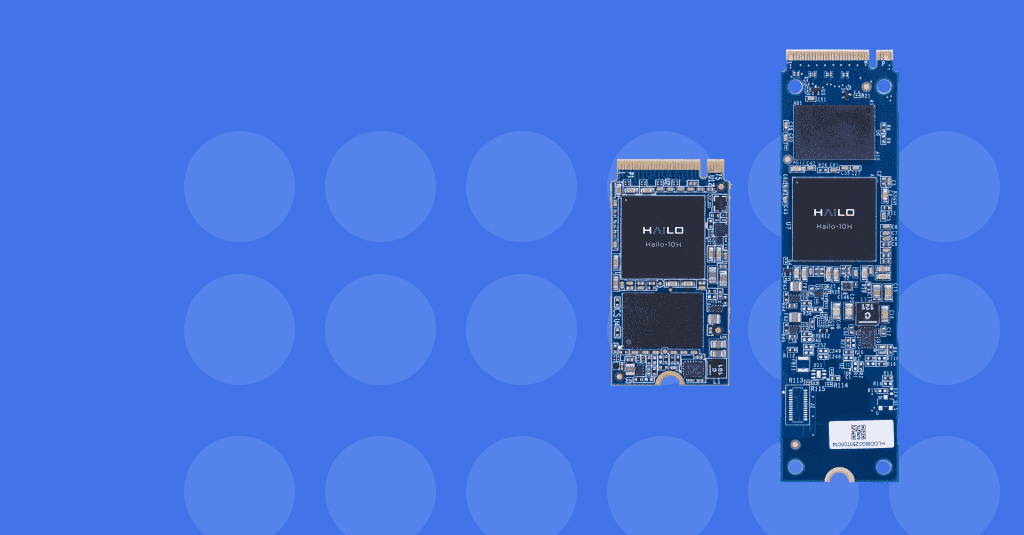
The Hailo-10H M.2 AI Acceleration Module HM22HB2C2XAE is a high-performance edge AI accelerator starter kit developed for systems that require local processing of demanding generative AI and computer vision workloads.
Powered by the Hailo-10H AI accelerator, the module delivers up to 40 TOPS at INT4 precision and 20 TOPS at INT8 precision. This enables compatible PCs and embedded edge systems to execute advanced neural-network inference locally, reducing dependence on cloud infrastructure and supporting low-latency AI processing.
The HM22HB2C2XAE variant uses the standard M.2 2280 Key M form factor and includes 4GB LPDDR4/4X on-module memory. The longer 2280 format is suitable for compatible M.2 Key M host systems that require additional AI processing capability while retaining a standardised module interface.
Host communication is provided through PCIe Gen 3.0 x4, enabling high-bandwidth communication between the accelerator and host processor. Hailo specifies support for both x86 and ARM host architectures, allowing integration into industrial computers, edge servers, embedded systems and AI-enabled PCs.
The Hailo-10H is designed for both vision AI and generative AI workloads. Suitable applications include computer vision, intelligent video analytics, image understanding, multimodal AI, supported large language models and vision-language models. Its architecture enables advanced AI processing to remain close to the source of data, which can improve responsiveness and reduce bandwidth usage.
The accelerator uses Hailo's second-generation structure-driven dataflow architecture, which is specifically designed around neural-network processing. This architecture enables efficient execution of deep-learning workloads while maintaining low power requirements.
Hailo specifies typical power consumption of approximately 2.5 W, making the module suitable for edge applications where energy efficiency and thermal constraints are important.
The Hailo software ecosystem supports widely used AI development frameworks including TensorFlow, TensorFlow Lite, Keras, PyTorch and ONNX. Supported operating systems include Linux, Windows and Android, providing flexibility across embedded, industrial and PC-based AI deployments.
The module is specified for industrial operation from -40°C to +85°C, making it suitable for industrial automation, robotics, smart infrastructure, intelligent transportation and other demanding edge environments.
By executing AI inference directly on the edge, the HM22HB2C2XAE can help reduce cloud traffic, improve response times and maintain AI functionality in systems where continuous cloud connectivity is not desirable or available.